The New Compute Foundationfor Physical AI.
Future Intelligence turns AI workloads into verified AI accelerator IP and subsystems—co-optimizing models and hardware for performance, power, and cost.
AI evolves fast. Your silicon should keep up.
AI workloads evolve faster than conventional accelerator design cycles can keep up. Changes in precision, memory, and data movement create new demands on hardware. FiLabs starts with your workload and product constraints, then co-designs the model and accelerator architecture to deliver verified IP tailored to your application.
Workload first.
Start with your AI model, latency requirements, power budget, and cost targets.Model and hardware, optimized together.
Explore precision, parallelism, memory, and data movement as a connected design problem.Verified for integration.
Receive accelerator IP with defined interfaces, verification evidence, and measured implementation results.Built into your design flow.
Bring the deliverables into your existing EDA tools and integration process.Start with one block. Build toward a subsystem.
Address an immediate bottleneck, then expand across your architecture and future product generations.A foundation for what comes next.
We are building a reusable foundation of accelerator architectures, verification assets, and optimization workflows.From AI workload to implementation-ready accelerator IP. We co-optimize the model and hardware architecture, carry the design through RTL and verification, and use measured implementation results to make the next decision better.
Start with the workload.
Optimize the system together.
Explore the choices that determine performance, power, area, and cost as one connected design problem.
Verified accelerator IP.
Implementation feedback informs the next architecture decision. AI agents accelerate the loop; engineers guide every trade-off.
Start with the customer need in front of you, then build toward the accelerator subsystem behind your product.
Workload-to-architecture co-design
Translate your AI workload and product targets into an accelerator architecture, balancing compute, memory, precision, and data movement.
Custom accelerator IP
Develop workload-specific compute and supporting digital blocks, delivered with verified RTL, documented interfaces, and implementation results.
IP optimization and verification
Improve existing blocks against performance, power, and area targets, with verification evidence to support integration.
Accelerator subsystem delivery
Combine compute, memory, and control into an integrated subsystem, with clearly scoped verification and implementation milestones.
TIME TO
FIRST PPA
DSE workload · elapsed daysDESIGN POINTS
PER UNIT TIME
DSE workload · throughputDSE COST
EFFICIENCY
DSE workload · cost efficiencyFUNCTIONAL
PASS RATE
RTL generation workload · Pass@1SYNTAX
FIX RATE
RTL syntax-debug workload · success rateFUNCTIONAL
FIX RATE
RTL functional-debug workload · success rate
FiLabs Joins OpenForge as Chip Design Partner for ComputeFi Silicon
FiLabs becomes OpenForge's first AI-native chip design partner — taking full-stack ownership of RTL, verification, and layout for ComputeFi's next-gen ZK accelerators.
↓28%
Logic Area Reduction
0.1 days
vs 4–5 weeks
100%
Equiv. Verified
28% Area Reduction on an Encryption Module — Without Touching Timing
FiLabs Spec-to-RTL Agent delivered 28% logic area reduction with 100% functional equivalence — in 0.1 days.
LLM-Aided Design
IEEE LAD 2025 Fellow
Celebrating Our Team's ICLAD Fellowship for GenChipUI!
Jinwei Tang named ICLAD Fellow for GenChipUI, a multi-agent framework for trustworthy LLM-aided chip design.
How AI Agents Will Define the Next Era of Chip Design
Our multi-agent platform automates the full silicon lifecycle from spec to tape-out.
Joined Arm Flexible Access for accelerated chip development
Partnering with Arm to accelerate AI-driven chip design and IP integration.
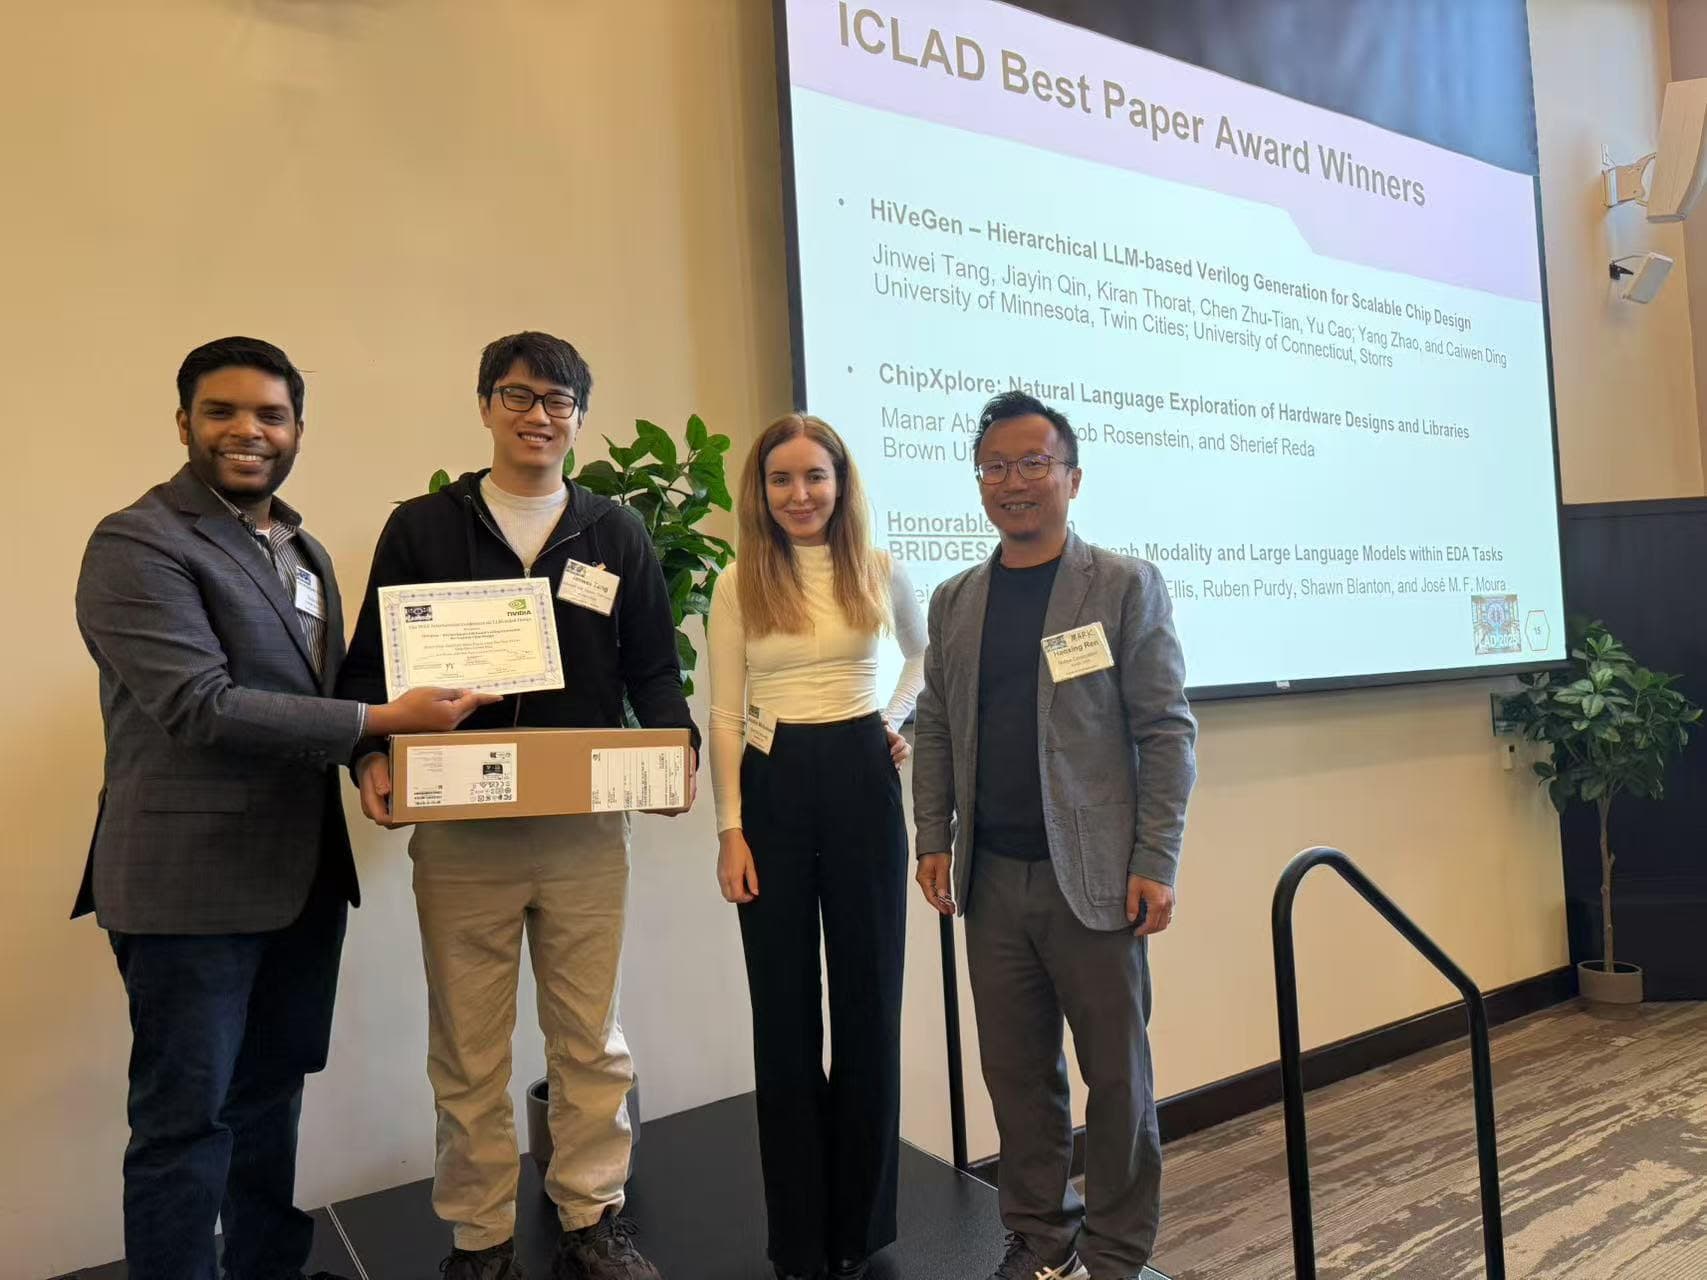
Hivegen: Hierarchical LLM-based Verilog generation
Our hierarchical Verilog generation framework won the ICLAD Best Paper Award.
Bring us your workload.
Start with your AI workload and your performance, power, and cost targets.
Define the first accelerator block.
Together, we identify the architecture and scope that addresses your most immediate bottleneck.
Build toward the subsystem.
Create a path from one verified block to the integrated accelerator subsystem behind your product.
Make custom silicon accessible.
Our vision is to make workload-specific silicon as accessible as cloud infrastructure.